Offline AI that reads thousands of messages so a competition lawyer reads the right ones.
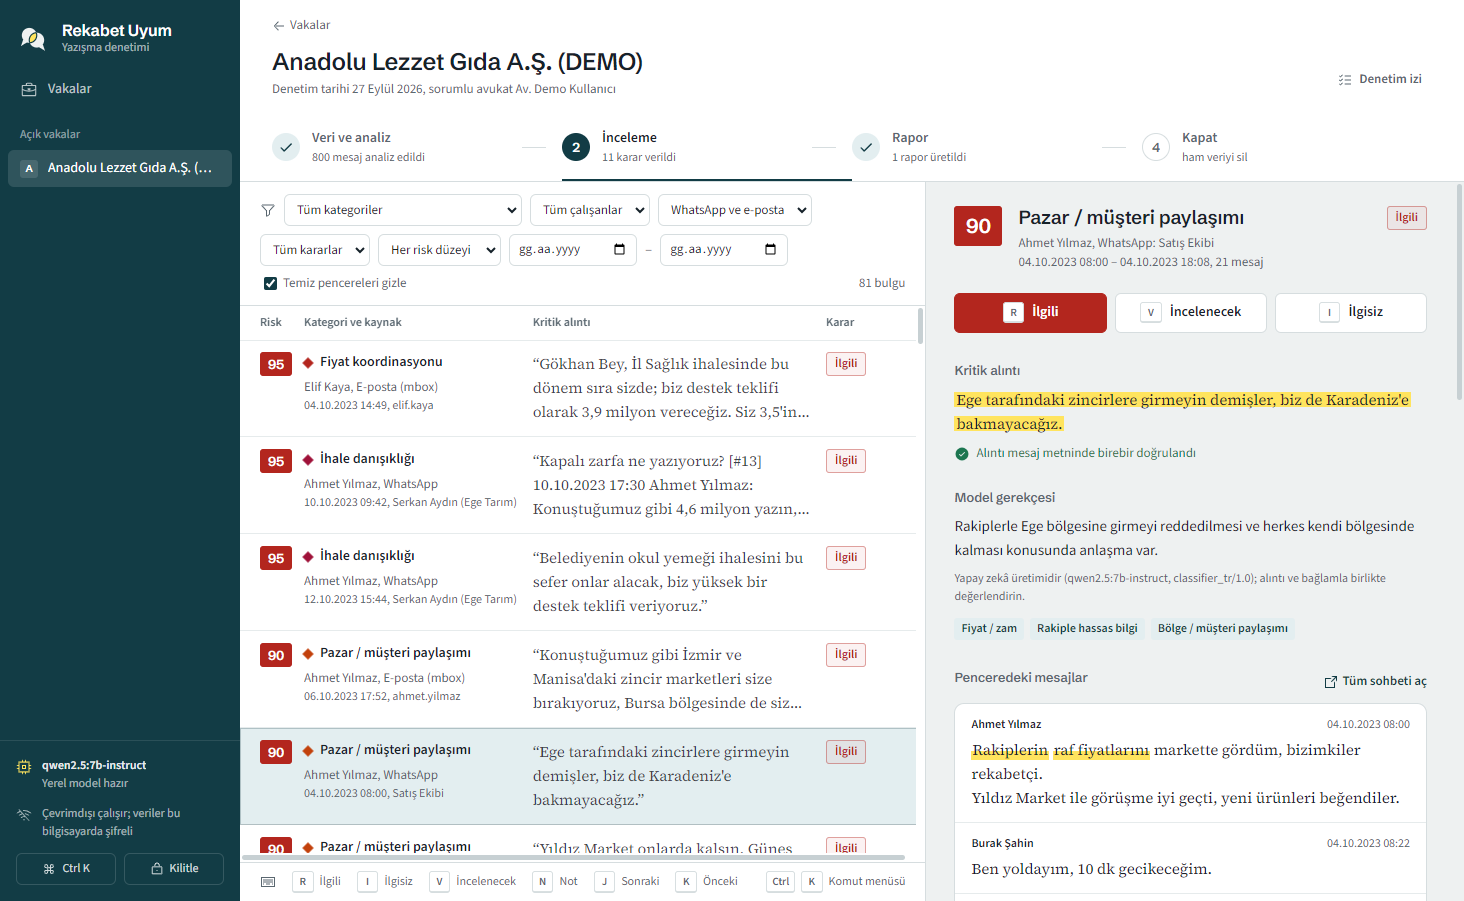
A desktop tool for a law team that ranks antitrust risk in employees' WhatsApp and e-mail, with the quote, the reasoning and similar Competition Board decisions next to every finding. Nothing leaves the lawyer's laptop.
The problem
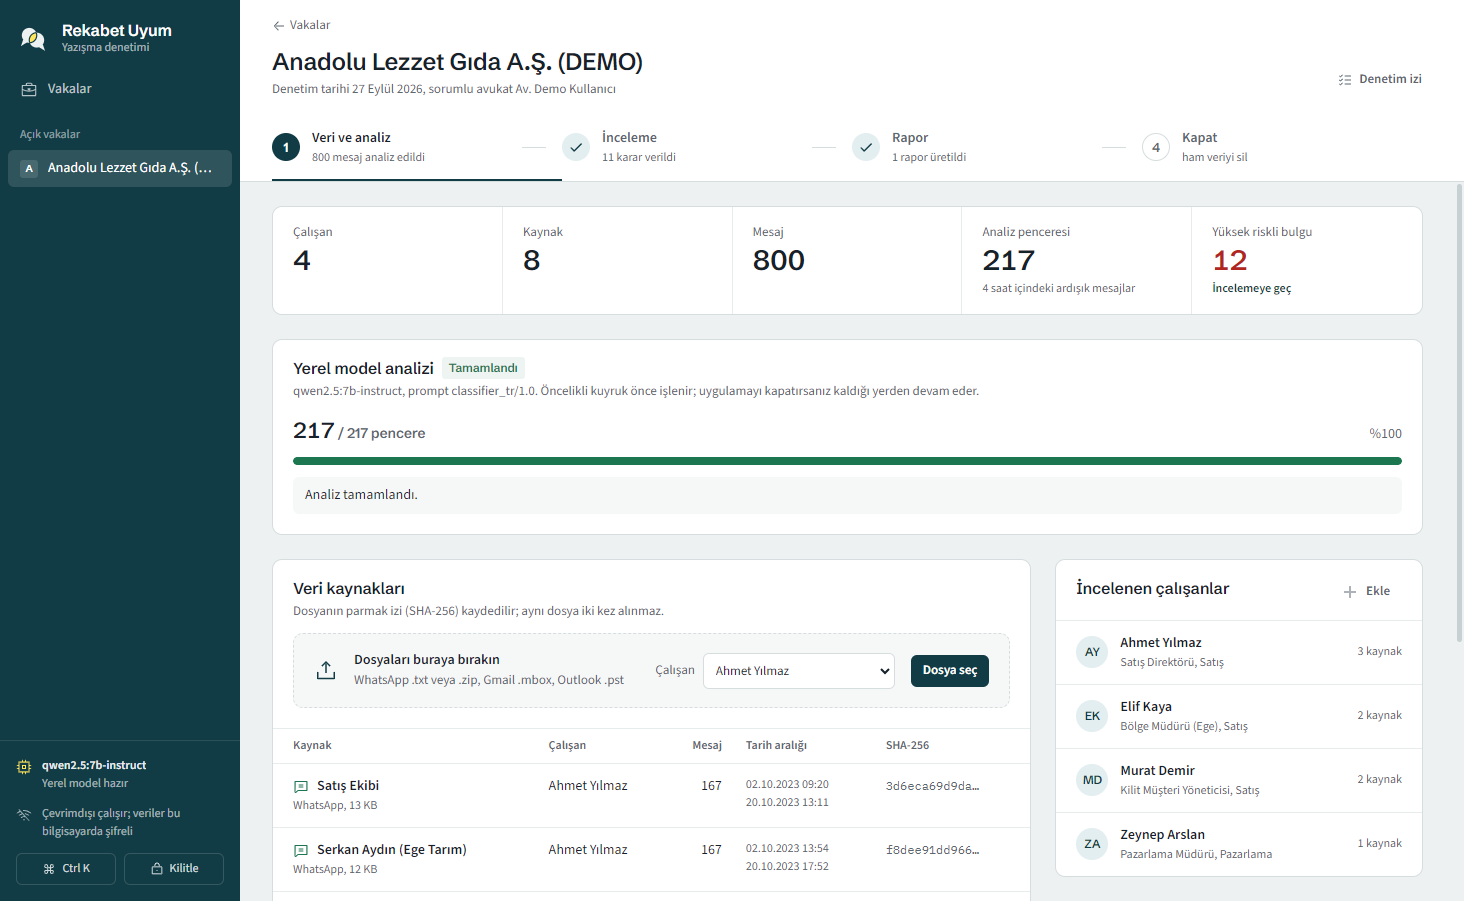
In a compliance audit or a dawn-raid preparation, a lawyer has to find the few messages that look like price fixing, market sharing, bid rigging or sensitive information exchange, inside tens of thousands of chats and e-mails.
Cloud AI is off the table: client data is privileged and can't leave the lawyer's machine. So the model has to run locally, on a laptop GPU, and still be good enough to trust.
"They said stay out of the Aegean chains, so we won't touch the Black Sea." A synthetic market-sharing message the tool flags at risk 90.
Results on a frozen test set
375 examples (339 from published Board decisions, 36 synthetic negatives), frozen before tuning so every round is measured against the same bar.
AUC by model
| Model | Threshold | Accuracy | False alarms | Missed | Category acc. | AUC |
|---|---|---|---|---|---|---|
| Gemma 4 12B, base (no tuning) | 50 | 0.747 | 10 | 85 | 0.46 | 0.82 |
| Round 8 · Qwen3-8B | 50 | 0.800 | 44 | 31 | 0.569 | 0.797 |
| Round 10 · Gemma 4 12B | 50 | 0.835 | 17 | 45 | 0.750 | 0.920 |
| Round 10 · Gemma 4 12B | 30 (val) | 0.888 | 32 | 10 | – | – |
| Claude Opus (reference) | 50 | 0.901 | 18 | 19 | 0.863 | 0.947 |
Threshold 30 was picked on the validation set, not the test set. It also matches the product's "needs review" band (30-79), so a lawyer sees borderline windows instead of losing them.
How it works
How the model got better
Data
- Collected all 10,469 published Competition Board decisions (329M characters) as a Turkish competition-law corpus.
- Extracted the real correspondence the Board treated as evidence, plus synthetic normal business chatter as negatives.
- Built a 12,049-row training set, including 8,674 windows labelled by Claude as a teacher model (distillation).
Training
- LoRA / QLoRA with Unsloth on Kaggle T4 and Modal A100 GPUs.
- Models tried: Qwen3.5-4B, Qwen3-8B, Qwen3-14B, Gemma 4 12B.
- Served locally through Ollama; bge-m3 embeddings for the precedent library.
Working with the lawyer
- Five versions of a written rule set, reviewed line by line.
- A 5-band risk scale and a keyword dictionary from the lawyer's revisions.
- Error reviews after every round, sorted into "model wrong" and "label debatable".
Privacy by design
- The back end listens only on 127.0.0.1; the model endpoint must be loopback too.
- The app window cancels every request that leaves the machine; a content security policy blocks external resources.
- Every case database on disk is encrypted with a key derived from the lawyer's master password.
- Closing a case writes the report, then deletes raw data and the case key.
- Training used only public Board decisions and synthetic data. No client data was ever uploaded.